Seedance 2.5 for AI UGC Ads: the real model, the real pipeline

Most people trying Seedance 2.5 type one prompt, get one 30-second clip, and judge the whole model off it
That's the wrong test. Seedance 2.5 isn't a slot machine you pull once - it's a reference-driven system
It was built to take up to 50 inputs (images, clips, audio) and hold them together across a single continuous scene
The people getting UGC ads out of it that pass as real footage aren't writing better one-line prompts
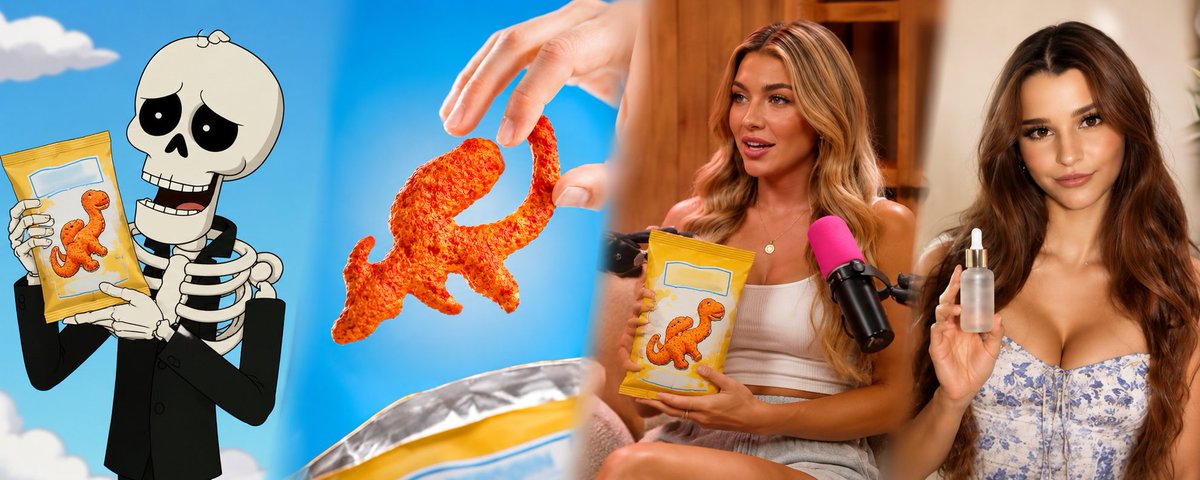
They're feeding it a pipeline: a consistent character, a scale-accurate product, a script reverse-engineered from something that already works, and a shot built in pieces instead of one long gamble
This article separates the two things that usually get blurred together in Seedance content: what the model actually does (verified against ByteDance's own spec), and what the workflow around it looks like when people who use it daily build UGC ads with it
Part 1 · What Seedance 2.5 actually is
Seedance 2.5 is ByteDance Seed's video generation model - the same team behind TikTok's AI stack
A few things about it are well-documented across multiple platforms offering it (Artlist, OpenArt, Topview, and others), not just marketing pages for one tool:
- Native 30-second single-pass generation. Earlier models forced you to generate short clips and stitch them. Seedance 2.5 can hold one scene together for a full 30 seconds without a cut, provided you're not asking for something structurally incompatible
- Up to 50 multimodal reference inputs per generation - 30 images, 10 video clips, 10 audio files. The model reads each one's role from your prompt: "this is the face," "this is the product," "this is the voice."
- Native audio. Sound, dialogue, and lip sync are generated in the same pass as the visuals - not layered on afterward. Put a line in quotes and the character says it on screen, synced
- Clip extension and continuation are supported natively, not just as a workaround - you can carry a shot's motion and pacing forward instead of generating a fresh, disconnected segment
- Clip extension and continuation are supported natively, not just as a workaround - you can carry a shot's motion and pacing forward instead of generating a fresh, disconnected segment
- Region-level editing - targeted changes to a specific part of a shot without regenerating the whole clip
- Resolution claims vary by platform - some list 1080p with 10-bit color, others advertise "4K." This is inconsistent across sources and worth checking on whatever platform you're actually using before you build a budget around it
That's the ceiling. Whether you hit it depends entirely on what you feed it - which is the part almost nobody explains well
Part 2 · Six techniques that actually move the needle
These come from creators who've spent real hours in the tool and published their exact prompt structures
They're technique, not hype - each one is a specific workaround for a specific failure mode
- Extend the clip, don't just generate it once. If you have a 10-second clip and need to know what happened before or after it, you don't re-prompt from scratch - you feed Seedance the existing clip and ask it to extend forward or backward from the last (or first) frame, matching pose, lighting, camera angle, and motion direction. This is the same mechanism behind "clip extension" in the official spec, applied deliberately instead of by accident
- **Stitch two clips with a described transition, not a hard cut.**If you have a "before" clip and an "after" clip that don't connect, you can prompt Seedance to generate the bridge: name video one as the before-clip, video two as the after-clip, describe a trigger action at the end of video one, describe the camera movement through the transition, and describe how it resolves into video two's opening frame. Done well, it reads as one continuous shot instead of two you spliced
- 3. Direct emotion through trigger and reaction, not just a label."She looks surprised" produces a flat, generic beat. Scripting the stimulus - a boom mic dips into frame, a phone buzzes, someone says a specific line - followed by the physical reaction in sequence (expression softens, mouth twitches, she breaks into laughter) produces something that reads as actual performance. You're writing stage direction, not an adjective
- **Feed it audio and let the character respond to it.**Upload up to 30 seconds of audio (a song, a radio bit, dialogue) and prompt the character to react - nodding to the beat, singing along, responding to a line. This is a direct use of the model's native audio-reference input, and it's one of the few ways to get audio-visual sync that doesn't feel like it was added in post
- **Screenshot your own output and feed it back in.**Generate a rough first pass, pull stills from the frames you actually like, then re-prompt using those stills as visual anchors - "preserve this outfit, this lighting, this pose, build a more coherent sequence around it." It's a feedback loop: your first generation becomes the reference material for your second, better one
- **Prompt camera work like a cinematographer, not a director.**Naming an angle (wide, close-up, low, overhead) and a movement (push-in, pan, orbit, dolly zoom) separately - rather than one vague phrase like "cinematic shot" - is what actually changes the output. If you don't know the vocabulary, describing what you want to see in plain terms and asking an LLM to translate it into camera language works fine; the model responds to the specific terms either way
Part 3 · The UGC ad pipeline, step by step
This is where three separate workflows - all independently built by different creators - converge on nearly the same sequence
That convergence is the actual signal here: when unrelated people land on the same five or six steps by trial and error, those steps are probably solving real failure modes, not just personal preference
Step 1 - Build a character that looks slightly imperfect, not flawless
A too-clean AI face reads as fake before anyone even watches the video
The creators who get realistic results generate several character candidates and deliberately pick the one with minor asymmetries or texture - the one that looks like an actual person who'd post on social media, not a rendered mannequin
Step 2 - Build a multi-angle reference sheet, not one face shot
A single portrait only tells the model what the front of the face looks like
Feeding it front, side, and physique references means later generations don't have to invent the rest of the person, which is where consistency breaks down across multiple clips
Step 3 - Feed the product image and the actual listing copy, not just a photo
Ingredients, benefits, how it's marketed - this is what keeps the dialogue from sounding vague or generic
A photo alone gives the model nothing to talk about; the model needs to know what it's supposedly recommending
Step 4 - Add a scale reference
This is the single most repeated fix across every source: put the product next to a hand, or another object of known size, in a reference image
Without it, the model has to guess proportions, and it guesses wrong often enough that regenerating a full video (not just an image) to fix it gets expensive fast
Step 5 - Generate in short segments, not one long clip
Even with 30-second native generation available, several workflows deliberately cap individual generations around 12–20 seconds
Cramming a full script into one pass increases the odds that dialogue rushes, pacing breaks, or something in the middle goes visibly wrong - and a failed 20-second generation costs more to redo than a failed 12-second one
Step 6 - Carry continuity between segments with saved frames
Save the last frame of one generated clip and feed it back in as a reference for the next one
This is what keeps the character, lighting, and setting from visibly shifting between segments that were technically generated separately
Step 7 - Assemble and edit inside one workflow where possible
Whether that's a timeline tool built into the generation platform or a separate editing pass, the fewer times you're exporting between disconnected tools, the fewer opportunities for something (captions, timing, audio sync) to break in the handoff
What to treat as a claim, not a fact
A few things circulating in Seedance UGC content are creator-reported, not independently verified, and worth holding at arm's length:
- Specific cost-per-video figures (e.g., "$11 per video" or comparisons to hiring a human UGC creator) come from individual creators' own reported spend on their own accounts, often tied to a paid course or community they're selling. Your actual cost depends on the platform, resolution, and how many regenerations your workflow needs - treat any single number as one data point, not a benchmark
- Claims about "indistinguishable from real people" are subjective and vary heavily by output - plenty of Seedance generations still show the tells (odd hand movement, slightly off audio sync, a background detail that doesn't hold up on close inspection)
- Resolution specs genuinely conflict across platforms hosting the model (1080p vs. "4K" claims). This isn't a case of one source being right and another wrong so much as different hosting platforms describing the same underlying model differently - check the specific platform you're using
The actual takeaway
Seedance 2.5's real advance isn't that it makes a "good enough" video from one prompt - plenty of models do that. It's that it's built to take a pile of references and hold them coherent across 30 seconds with synced audio
That only pays off if you actually feed it the pile: a character sheet instead of one photo, a scale reference instead of a guess, a script reverse-engineered from something proven instead of written blind, and short verified segments instead of one expensive roll of the dice
The model does the rendering. The pipeline is still yours to build
Related articles

ranking every AI video model for creating AI UGC...
most model rankings are built on which one makes the prettiest 5 second demo.

the ultimate guide on creating "skeleton" AI UGC animations...
a skeleton talking to camera about your product sounds like a joke.