Claude Code + NotebookLM + Obsidian: Research Monster That Gets Smarter Every Time You Use It

Most people treat research as a manual task.
You open 10 tabs. You watch videos. You read articles. You take notes somewhere. An hour later you have a pile of information you're not sure what to do with.
There is a better way.
This is a step-by-step guide to building a research workflow using Claude Code, NotebookLM, and Obsidian that can investigate any topic - market dynamics, emerging technologies, crypto ecosystems, content niches, anything - and gets sharper every time you use it.
Setup time: under 30 minutes
The Stack and Why It Works
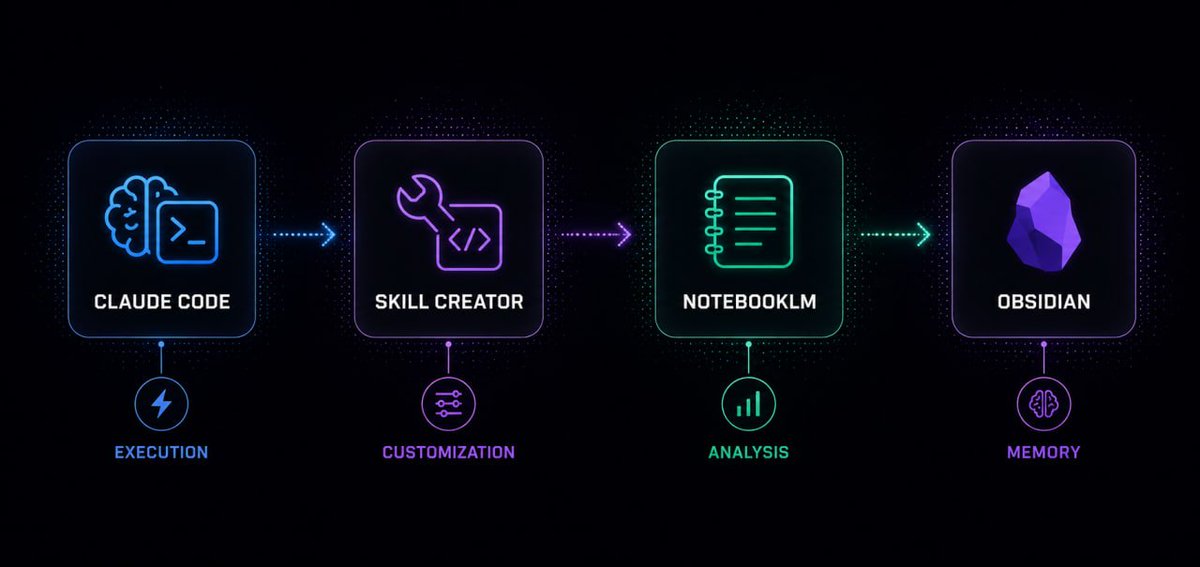
Four tools. Each one handles a different layer of the problem.
- Claude Code - the execution engine. It runs commands, calls skills, manages files, and orchestrates the entire pipeline. You talk to it in plain language, it does the work.
- Skill Creator - the customization layer. A Claude Code plugin that lets you build reusable skills in natural language. You describe what you want, it generates the code and installs the skill. No programming required.
- NotebookLM - the analysis engine. Google's AI research tool that reads your sources and generates deep analysis, summaries, infographics, flashcards, podcast scripts, and more. When Claude Code offloads processing to NotebookLM, it's using Google's compute, not your Claude tokens.
- Obsidian - the memory layer. A local markdown-based knowledge system that stores everything the workflow produces. Over time Claude Code reads these files and learns how you think, what you care about, and how you want your analysis delivered.
Combined: a research system that executes on command, analyzes at scale, and improves with use.
Step 1: Install the Skill Creator
Open Claude Code. Make sure you are inside your Obsidian vault folder - this is important for Obsidian to pick up the files Claude Code generates.
Run this command:
/plugin
Search for skill-creator. Install it. Exit Claude Code. Restart Claude Code.
You now have the ability to create any skill by describing it in plain language

Step 2: Create the YouTube Search Skill
This skill is what allows Claude Code to search YouTube and pull structured video data - titles, channels, subscriber counts, view counts, upload dates, URLs, and engagement ratios.
Run this command inside Claude Code:
/skill-creator I want to create a skill that searches
YouTube and returns structured video results.
It should use yt-dlp to search for videos by query,
return the top 20 results by default, and include
metadata for each video - title, channel name, subscriber
count, view count, duration, upload date, and URL.
It should filter to the last 6 months by default but support
a --months flag to change that.
It should also calculate a views-to-subscribers
ratio as an engagement metric.
The output should be nicely formatted with
dividers between each result and human-readable numbers.
Claude Code will generate the skill, install it, and confirm. You now have /yt-search available as a command.
Note: yt-dlp needs to be installed on your machine. If you don't have it
Step 3: Install NotebookLM-py
NotebookLM does not have a public API. To connect Claude Code to NotebookLM, we use an open-source project called notebooklm-py.
Repository: github. com/teng-lin/notebooklm-py
Run these commands in your terminal (not inside Claude Code - open a separate terminal window):
pip install notebooklm-py
Then authenticate:
notebooklm login
A browser window will open. Log into your Google account. Done. The connection is established

Step 4: Create the NotebookLM Skill
Now you need to teach Claude Code how to use notebooklm-py. Run this inside Claude Code:
/skill-creator create a skill so we can best use the
notebooklm-py tool. Reference the GitHub repo at
github. com/teng-lin/notebooklm-py and build
a skill that can: create new notebooks, add sources
(YouTube URLs, text, files), run analysis on those sources,
and generate deliverables including audio overview,
mindmap, flashcards, and infographic.
This gives Claude Code a full NotebookLM skill with commands for every action NotebookLM supports - up to 50 sources per notebook, all deliverable types.
Step 5: Combine Everything Into One Pipeline Skill
This is where the workflow becomes genuinely powerful.
Instead of manually running the YouTube search, then sending results to NotebookLM, then requesting analysis - you build one skill that does all of it in sequence on a single command.
Run this inside Claude Code:
/skill-creator I want to create a YouTube research pipeline
skill that combines the yt-search skill and the
NotebookLM skill. When I use this pipeline skill I want
it to: take what I told it to research, go to YouTube and
find 10 relevant videos using the yt-search skill, use
the NotebookLM skill to create a new notebook,
add those video sources to the notebook, then do
analysis on the topic based on what I said when
I invoked the skill. Furthermore ask me if I want
a deliverable - NotebookLM can create flashcards,
infographics, mindmaps, audio overviews.
If I don't specify a deliverable assume none.
After analysis bring everything back to me in a
 markdown file saved to the vault, and also show
it in chat. Include all YouTube search metadata
in the output - sources used, view counts,
channel names, engagement ratios.

Running the Workflow
/yt-pipeline I want to research AI agent frameworks in 2026.
Which frameworks are developers actually adopting -
- LangGraph, CrewAI, AutoGen, Agno, or something else?
I want to understand what's driving views on this topic,
where there's disagreement in the community,
what the outliers are, and what angles haven't been
covered well yet. Find 10 relevant sources,
push them to a new NotebookLM notebook,
run a full analysis, and generate an infographic
showing the landscape.
With the pipeline skill installed, this is what an actual research session looks like.
The topic: AI agent frameworks. What's actually gaining traction in 2026, what's overhyped, and where the gaps are in existing coverage.
Claude Code starts the pipeline. It calls the YouTube search skill, finds 10 videos across framework tutorials, comparisons, and developer takes - passes the URLs to NotebookLM, creates a notebook, runs analysis, and requests an infographic.
Total processing time: around 6 minutes.
Most of that time is NotebookLM processing on Google's servers - not your Claude tokens.
The result comes back as:
- A full analysis covering which frameworks are rising vs. plateauing, what developers are actually complaining about, engagement outliers, and content gaps nobody has covered yet
- An infographic mapping the AI agent framework landscape
- A markdown file saved directly into your Obsidian vault with everything structured and linked - ready to reference in future research sessions

Where Obsidian Makes It a Different Tool Entirely
Everything above works as a one-time research task.
Obsidian is what turns it into something that compounds.
Every markdown file the workflow produces lands in your Obsidian vault. Over time your vault becomes a structured corpus of everything you've researched - topics, sources, analysis, patterns, conclusions.
Claude Code can read all of these files. It sees how they're linked. It understands what topics you return to, what analysis you found useful, what format you prefer.
The claude.md file inside your vault is where this becomes explicit. It's a configuration file that tells Claude Code how to work with you - your conventions, your output preferences, how you want things structured.
You update it by saying:
Can we update claude.md so it better reflects
my work style, analysis approach, and output
preferences based on our latest conversations?
Claude Code reads the recent session, identifies your patterns, and updates the file.
Do this once a week. After a month the workflow knows you well enough that outputs start matching what you actually want without extensive prompting.
After a year - if you're doing this consistently - you have a research system that has absorbed hundreds of sessions, understands your thinking style, and operates as a trained assistant rather than a blank tool.

The Modular Point Nobody Mentions
The YouTube source is not the point.
The pipeline structure is the point.
You can replace YouTube with any data source Claude Code can access:
- PDFs - academic papers, industry reports, whitepapers
- Public web pages - news articles, documentation, blog posts
- Local files - your own notes, exported data, transcripts
- Google Drive - documents and spreadsheets you already have
The workflow template stays the same. Swap the source, keep the structure.
Research a crypto ecosystem using whitepapers and public documentation. Analyze an emerging technology using conference talks on YouTube. Map a content niche by analyzing what's performing. Study market dynamics using public reports.
Whatever the use case - the pipeline, the analysis layer, and the memory system remain identical.
What You End Up With
A research system that:
- Executes full research pipelines on a single command
- Offloads heavy analysis to Google's infrastructure via NotebookLM
- Produces structured deliverables - infographics, mindmaps, audio, flashcards - automatically
- Saves every result to a local knowledge base
- Learns your preferences over time and improves its outputs accordingly
The 30-minute setup pays for itself the first time you use it
Related articles
5 Hacks to Instantly Level Up Your AI Second Brain
The number one question I get right now is how my AI operating system is organized. Where files should route, how wikis should be structured, where client projects go.

this system will change your life...
"build me a personal knowledge vault at ~/vault. create numbered top-level folders so you can always find things predictably: 00-inbox for raw material i haven't reviewed, 10-identity for who i am an…

Claude + Obsidian = $1M YouTube on Autopilot
Most content creators use AI as a temporary worker with amnesia. Every time they open a new chat to write a script, they waste tokens and time re-explaining their niche, target audience, brand voice,…