pgContext: Full AI search engine inside Postgres (Open Source)

5.3× faster than pgvector, with hybrid retrieval, filter-aware vector search, and exact re-scoring built in. Read on for the core capabilities and benchmarks, and free hosted option.
Today, we’re launching pgContext: an open-source Postgres extension that turns the database you already run into a full AI search engine. No extra database required.
pgContext core capabilities:
> TLDR: you can now use metadata filters alongside vectors without having to build indexes
pgContext provides the retrieval features you’d expect from a dedicated vector engine while keeping your application data, vectors, permissions, filters, backups, and replication inside PostgreSQL.

- Exact vector search and persisted, page-native HNSW indexes
- L2, inner-product, cosine, and L1 distance metrics
- Filter-aware ANN over registered columns and JSONB paths
- Exact-score rechecks under PostgreSQL MVCC, ACLs, and RLS
- Collections, scrolling, counts, facets, and grouping
- Dense and full-text hybrid retrieval with reciprocal-rank fusion
Everything in the database you already love. Sometimes maybe too much. It's ok. Postgres deserves all the love it can get.
Benchmarks
On the standard GloVe-100-angular benchmark (1,183,514 vectors using cosine distance) pgContext delivered the same recall as pgvector with 3.8× to 5.3× lower median query latency.
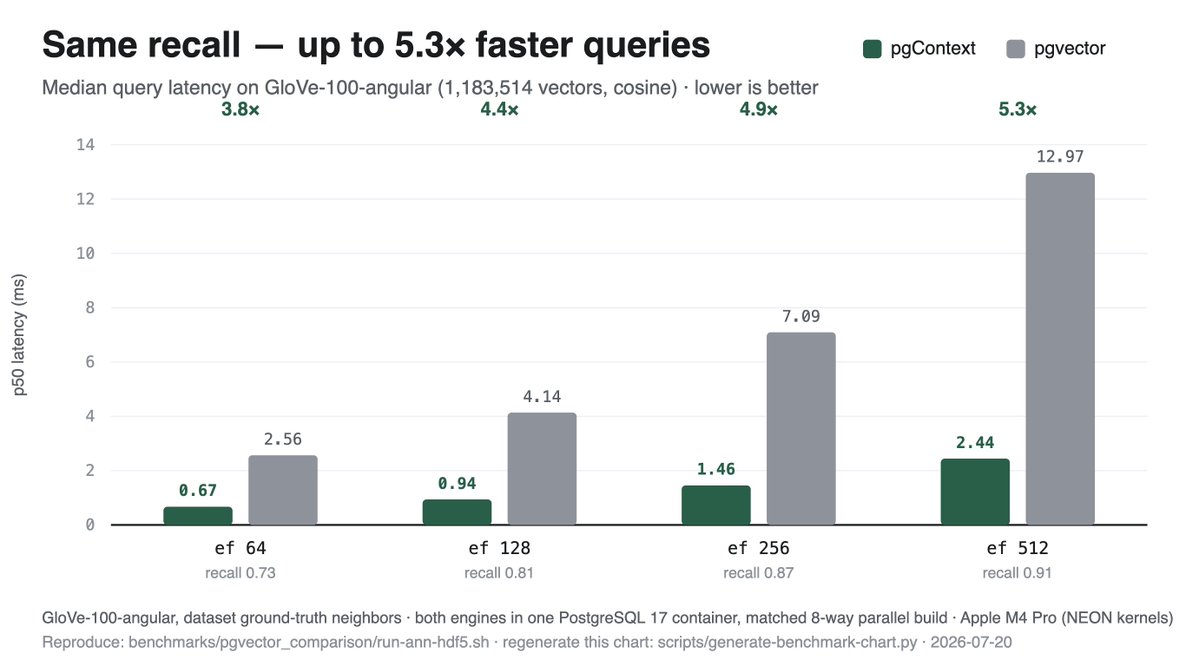 — "Standard GloVe-100-angular benchmark. "
Both extensions were tested in the same PostgreSQL 17 container with the same eight-way parallel build budget on an Apple M4 Pro (That's what @daltonmeon is using)
The advantage grows as you increase the recall target. At approximately 0.91 recall@10, pgContext answered queries in 2.44 ms, compared with 12.97 ms for pgvector.
That performance can also be spent on quality: within the same latency budget, pgContext can search more of the graph and return higher-recall results.
Hybrid retrieval without application glue
Semantic similarity is not enough for every query. Product names, identifiers, exact phrases, error codes, and rare terms often benefit from lexical search.
pgContext combines dense vector retrieval with PostgreSQL full-text search and fuses both rankings using reciprocal-rank fusion.
No separate search service. No manual result-merging layer. No duplicated authorization model.
Just one retrieval system, running where your data already lives.
pgContext is open source under Apache 2.0.
We’re a three-person team, so every GitHub star is both a metric and a small emotional support animal.
Clone it. Benchmark it. Throw Claude Code at it. Break it in ways we haven’t thought of yet. Open issues. Tell us what’s missing.
And if it looks useful, please star the repo. If it doesn’t look useful yet, star it optimistically and then tell us why. ⭐
GitHub → [Click Here]
Host on Polygres → [Click Here] (Free for limited time)
More Links Below!
Related articles

how to run an ai native agency with jev (FULL GUIDE)
jev is open to everyone now. it's a super fast decision model, so one person can now do work that businesses usually pay an agency a big cut for. here's how you can set up a whole ai native agency wi…

5 Step Video GEO Guide for SaaS (62k AI Mentions in 3 Months with Claude)
I pulled every "best ... software" keyword with real US search volume, 2,328 of them, and ran 140 through DataForSEO on Google US mobile on September 1, 2026: the 60 biggest category head terms plus…